api-ref: custom API reference (#4770)
* initialized next.js project

* finished markdown sections

* added operation schema component

* change page metadata

* eslint fixes

* fixes related to deployment

* added response schema

* resolve max stack issue

* support for different property types

* added support for property types

* added loading for components

* added more loading

* type fixes

* added oneOf type

* removed console

* fix replace with push

* refactored everything

* use static content for description

* fixes and improvements

* added code examples section

* fix path name

* optimizations

* fixed tag navigation

* add support for admin and store references

* general enhancements

* optimizations and fixes

* fixes and enhancements

* added search bar

* loading enhancements

* added loading

* added code blocks

* added margin top

* add empty response text

* fixed oneOf parameters

* added path and query parameters

* general fixes

* added base path env variable

* small fix for arrays

* enhancements

* design enhancements

* general enhancements

* fix isRequired

* added enum values

* enhancements

* general fixes

* general fixes

* changed oas generation script

* additions to the introduction section

* added copy button for code + other enhancements

* fix response code block

* fix metadata

* formatted store introduction

* move sidebar logic to Tags component

* added test env variables

* fix code block bug

* added loading animation

* added expand param + loading

* enhance operation loading

* made responsive + improvements

* added loading provider

* fixed loading

* adjustments for small devices

* added sidebar label for endpoints

* added feedback component

* fixed analytics

* general fixes

* listen to scroll for other headings

* added sample env file

* update api ref files + support new fields

* fix for external docs link

* added new sections

* fix last item in sidebar not showing

* move docs content to www/docs

* change redirect url

* revert change

* resolve build errors

* configure rewrites

* changed to environment variable url

* revert changing environment variable name

* add environment variable for API path

* fix links

* fix tailwind settings

* remove vercel file

* reconfigured api route

* move api page under api

* fix page metadata

* fix external link in navigation bar

* update api spec

* updated api specs

* fixed google lint error

* add max-height on request samples

* add padding before loading

* fix for one of name

* fix undefined types

* general fixes

* remove response schema example

* redesigned navigation bar

* redesigned sidebar

* fixed up paddings

* added feedback component + report issue

* fixed up typography, padding, and general styling

* redesigned code blocks

* optimization

* added error timeout

* fixes

* added indexing with algolia + fixes

* fix errors with algolia script

* redesign operation sections

* fix heading scroll

* design fixes

* fix padding

* fix padding + scroll issues

* fix scroll issues

* improve scroll performance

* fixes for safari

* optimization and fixes

* fixes to docs + details animation

* padding fixes for code block

* added tab animation

* fixed incorrect link

* added selection styling

* fix lint errors

* redesigned details component

* added detailed feedback form

* api reference fixes

* fix tabs

* upgrade + fixes

* updated documentation links

* optimizations to sidebar items

* fix spacing in sidebar item

* optimizations and fixes

* fix endpoint path styling

* remove margin

* final fixes

* change margin on small devices

* generated OAS

* fixes for mobile

* added feedback modal

* optimize dark mode button

* fixed color mode useeffect

* minimize dom size

* use new style system

* radius and spacing design system

* design fixes

* fix eslint errors

* added meta files

* change cron schedule

* fix docusaurus configurations

* added operating system to feedback data

* change content directory name

* fixes to contribution guidelines

* revert renaming content

* added api-reference to documentation workflow

* fixes for search

* added dark mode + fixes

* oas fixes

* handle bugs

* added code examples for clients

* changed tooltip text

* change authentication to card

* change page title based on selected section

* redesigned mobile navbar

* fix icon colors

* fix key colors

* fix medusa-js installation command

* change external regex in algolia

* change changeset

* fix padding on mobile

* fix hydration error

* update depedencies
This commit is contained in:
 Shahed Nasser authored and
 GitHub committed
1 parent
16249ec280
commit
914d773d3a
3270 files changed
+22075
-192064
No files matched your search
@@ -0,0 +1,27 @@
|
||||
---
|
||||
description: "Learn about Medusa's architecture and get a general overview of how all different tools work together."
|
||||
---
|
||||
|
||||
# Medusa Architecture Overview
|
||||
|
||||
In this document, you'll get an overview of Medusa's architecture to better understand how all resources and tools work together.
|
||||
|
||||
## Architecture Overview
|
||||
|
||||
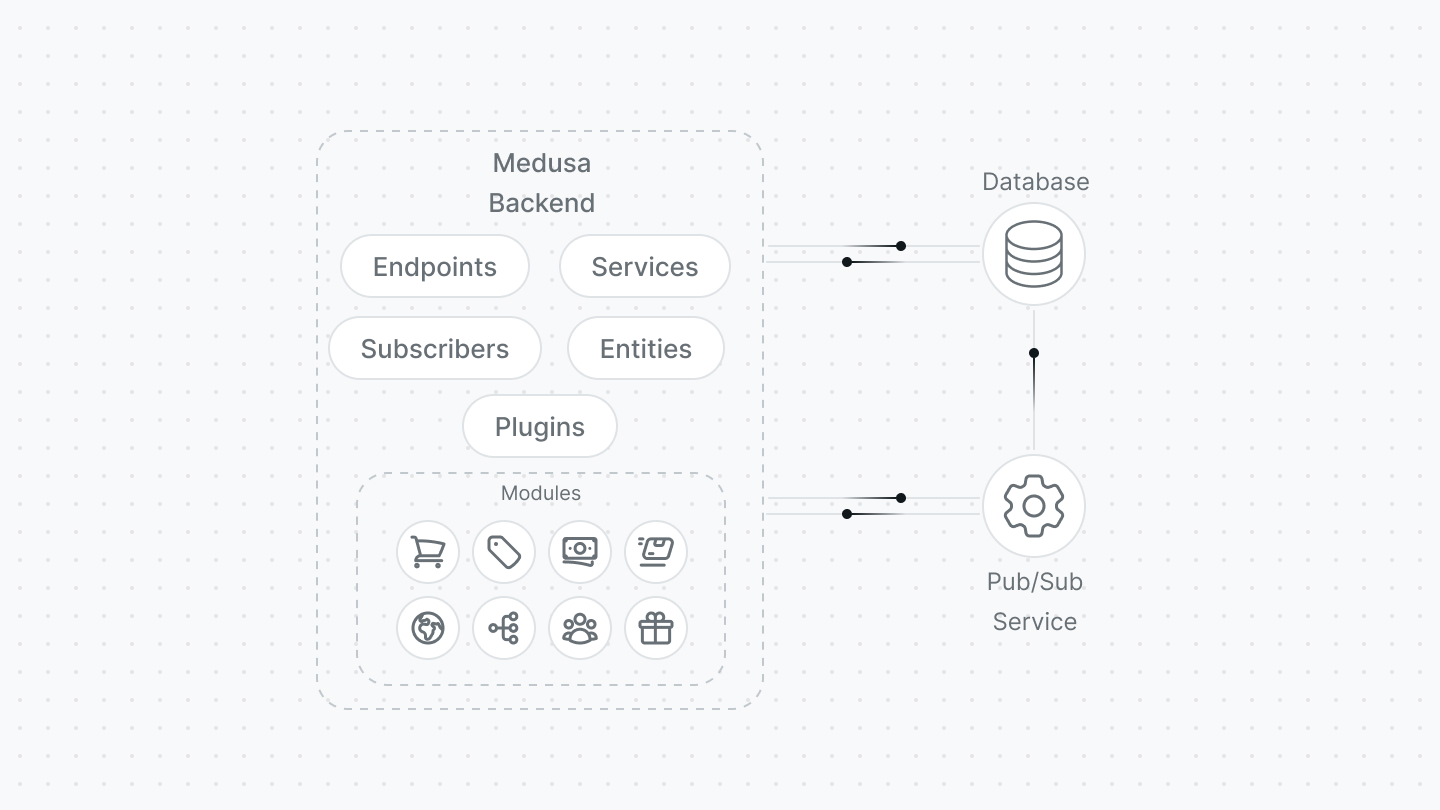
Medusa's core package `@medusajs/medusa` is a Node.js backend built on top of [Express](https://expressjs.com/). It combines all the [**Commerce Modules**](../../modules/overview.mdx) that Medusa provides. Commerce Modules are ecommerce features that can be used as building blocks in an ecommerce ecosystem. Product is an example of a Commerce Module.
|
||||
|
||||
|
||||
|
||||
The backend connects to a **database**, such as [PostgreSQL](https://www.postgresql.org/), to store the ecommerce store’s data. The tables in that database are represented by [**Entities**](../entities/overview.mdx), built on top of [Typeorm](https://typeorm.io/). Entities can also be reflected in the database using [**Migrations**](../entities/migrations/overview.mdx).
|
||||
|
||||
The retrieval, manipulation, and other utility methods related to that entity are created inside a [**Service**](../services/overview.mdx). Services are TypeScript or JavaScript classes that, along with other resources, can be accessed throughout the Medusa backend through [**dependency injection**](./dependency-injection.md).
|
||||
|
||||
The backend does not have any tightly-coupled frontend. Instead, it exposes [**Endpoints**](../endpoints/overview.mdx) which are REST APIs that frontends such as an admin or a storefront can use to communicate with the backend. Endpoints are [Express routes](https://expressjs.com/en/guide/routing.html).
|
||||
|
||||
Medusa also uses an [**Events Architecture**](../events/index.mdx) to trigger and handle events. Events are triggered when a specific action occurs, such as when an order is placed. To manage this events system, Medusa connects to a service that implements a pub/sub model, such as [Redis](https://redis.io/).
|
||||
|
||||
Events can be handled using [**Subscribers**](../events/subscribers.mdx). Subscribers are TypeScript or JavaScript classes that add their methods as handlers for specific events. These handler methods are only executed when an event is triggered.
|
||||
|
||||
You can create any of the resources in the backend’s architecture, such as entities, endpoints, services, and more, as part of your custom development without directly modifying the backend itself. The Medusa backend uses [**loaders**](../loaders/overview.mdx) to load the backend’s resources, as well as your custom resources and resources in [**Plugins**](../plugins/overview.mdx).
|
||||
|
||||
You can package your customizations into Plugins to reuse them in different Medusa backends or publish them for others to use. You can also install existing plugins into your Medusa backend.
|
||||
@@ -0,0 +1,735 @@
|
||||
---
|
||||
description: 'Learn what the dependency container is and how to use it in Medusa. Learn also what dependency injection is, and what the resources registered and their names are.'
|
||||
---
|
||||
|
||||
# Dependency Container and Injection
|
||||
|
||||
In this document, you’ll learn what the dependency container is and how you can use it in Medusa with dependency injection.
|
||||
|
||||
## Introduction
|
||||
|
||||
### What is Dependency Injection
|
||||
|
||||
Dependency Injection is the act of delivering the required resources to a class. These resources are the class’s dependencies. This is usually done by passing (or injecting) the dependencies in the constructor of the class.
|
||||
|
||||
Generally, all resources are registered in a container. Then, whenever a class depends on one of these resources, the system retrieves the resources from the container and injects them into the class’s constructor.
|
||||
|
||||
### Medusa’s Dependency Container
|
||||
|
||||
Medusa uses a dependency container to register essential resources of the backend. You can then access these resources in classes and endpoints using the dependency container.
|
||||
|
||||
For example, if you create a custom service, you can access any other service registered in Medusa in your service’s constructor. That includes Medusa’s core services, services defined in plugins, or other services that you create on your backend.
|
||||
|
||||
You can load more than services in your Medusa backend. You can load the Entity Manager, logger instance, and much more.
|
||||
|
||||
### MedusaContainer
|
||||
|
||||
To manage dependency injections, Medusa uses [Awilix](https://github.com/jeffijoe/awilix). Awilix is an NPM package that implements dependency injection in Node.js projects.
|
||||
|
||||
When you run the Medusa backend, a container of the type `MedusaContainer` is created. This type extends the [AwilixContainer](https://github.com/jeffijoe/awilix#the-awilixcontainer-object) object.
|
||||
|
||||
The backend then registers all important resources in the container, which makes them accessible in classes and endpoints.
|
||||
|
||||
---
|
||||
|
||||
## Registered Resources
|
||||
|
||||
The Medusa backend scans the core Medusa package, plugins, and your files in the `dist` directory and registers the following resources:
|
||||
|
||||
:::tip
|
||||
|
||||
The Lifetime column indicates the lifetime of a service. Other resources that aren't services don't have a lifetime, which is indicated with the `-` in the column. You can learn about what a lifetime is in the [Create a Service](../services/create-service.mdx) documentation.
|
||||
|
||||
:::
|
||||
|
||||
<table class="reference-table table-col-4">
|
||||
<thead>
|
||||
<tr>
|
||||
<th>
|
||||
|
||||
Resource
|
||||
|
||||
</th>
|
||||
<th>
|
||||
|
||||
Description
|
||||
|
||||
</th>
|
||||
|
||||
<th>
|
||||
|
||||
Registration Name
|
||||
|
||||
</th>
|
||||
<th>
|
||||
|
||||
Lifetime
|
||||
|
||||
</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Configurations
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
The configurations that are exported from `medusa-config.js`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`configModule`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Services
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Services that extend the `TransactionBaseService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Each service is registered under its camel-case name. For example, the `ProductService` is registered as `productService`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Core services by default have the `SINGLETON` lifetime. However, some have a different lifetime which is indicated in this table. Custom services, including services in plugins, by default have the `SCOPED` lifetime, unless defined differently within the custom service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Entity Manager
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of Typeorm’s Entity Manager.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`manager`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Logger
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of Medusa CLI’s logger. You can use it to log messages to the terminal.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`logger`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Payment Processor
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every payment processor that extends the `AbstractPaymentService` or the `AbstractPaymentProcessor` classes.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Every payment processor is registered under two names:
|
||||
|
||||
- Its camel-case name of the processor. For example, the `StripeProviderService` is registered as `stripeProviderService`.
|
||||
- `pp_` followed by its identifier. For example, the `StripeProviderService` is registered as `pp_stripe`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the payment processor service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Payment Processors
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of all payment processor that extend the `AbstractPaymentService` or `AbstractPaymentProcessor` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`paymentProviders`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`paymentProviders` is `TRANSIENT`, and each item in it is `SINGLETON`.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Fulfillment Provider
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every fulfillment provider that extends the `FulfillmentService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Every fulfillment provider is registered under two names:
|
||||
|
||||
- Its camel-case name. For example, the `WebshipperFulfillmentService` is registered as `webshipperFulfillmentService`.
|
||||
- `fp_` followed by its identifier. For example, the `WebshipperFulfillmentService` is registered as `fp_webshipper`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the fulfillemnt provider service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Fulfillment Providers
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of all fulfillment providers that extend the `FulfillmentService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`fulfillmentProviders`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`fulfillmentProviders` is `TRANSIENT`, and each item in it is `SINGLETON`.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Notification Provider
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every notification provider that extends the `AbstractNotificationService` or the `BaseNotificationService` classes.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Every notification provider is registered under two names:
|
||||
|
||||
- Its camel-case name. For example, the `SendGridService` is registered as `sendGridService`.
|
||||
- `noti_` followed by its identifier. For example, the `SendGridService` is registered as `noti_sendgrid`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the notification provider service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Notification Providers
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of all notification providers that extend the `AbstractNotificationService` or the `BaseNotificationService` classes.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`notificationProviders`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`notificationProviders` is `TRANSIENT`, and each item in it is `SINGLETON`.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
File Service
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the class that extends the `FileService` class, if any.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
The file service is registered under two names:
|
||||
|
||||
- Its camel-case name. For example, the `MinioService` is registered as `minioService`.
|
||||
- `fileService`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the file service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Search Service
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the class that extends the `AbstractSearchService` or the `SearchService` classes, if any.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
The search service is registered under two names:
|
||||
|
||||
- Its camel-case name. For example, the `AlgoliaService` is registered as `algoliaService`.
|
||||
- `searchService`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the search service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Tax Provider
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every tax provider that extends the `AbstractTaxService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
The tax provider is registered under two names:
|
||||
|
||||
- Its camel-case name.
|
||||
- `tp_` followed by its identifier.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the tax provider service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Tax Providers
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of every tax provider that extends the `AbstractTaxService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`taxProviders`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`taxProviders` is `TRANSIENT`, and each item in it is `SINGLETON`.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Oauth Services
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every service that extends the `OauthService` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Each Oauth Service is registered under its camel-case name followed by `Oauth`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
By default, it's `SINGLETON` unless defined differently within the Oauth service.
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Feature Flag Router
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the `FlagRouter`. This can be used to list feature flags, set a feature flag’s value, or check if they’re enabled.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`featureFlagRouter`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Redis
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the Redis client. If Redis is not configured, a fake Redis client is registered.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`redisClient`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Entity
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every entity.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Each entity is registered under its camel-case name followed by Model. For example, the `CustomerGroup` entity is stored under `customerGroupModel`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Entities
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of all database entities that is passed to Typeorm when connecting to the database.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`db_entities`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Repositories
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of each repository.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Each repository is registered under its camel-case name. For example, `CustomerGroupRepository` is stored under `customerGroupRepository`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Single Batch Job Strategy
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of every class extending the `AbstractBatchJobStrategy` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Each batch job strategy is registered under three names:
|
||||
|
||||
- Its camel-case name. For example, `ProductImportStrategy` is registered as `productImportStrategy`.
|
||||
- `batch_` followed by its identifier. For example, the `ProductImportStrategy` is registered under `batch_product-import-strategy`.
|
||||
- `batchType_` followed by its batch job type. For example, the `ProductImportStrategy` is registered under `batchType_product-import`.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
All Batch Job Strategies
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An array of all classes extending the `AbstractBatchJobStrategy` abstract class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`batchJobStrategies`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Tax Calculation Strategy
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the class implementing the `ITaxCalculationStrategy` interface.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`taxCalculationStrategy`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Cart Completion Strategy
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the class extending the `AbstractCartCompletionStrategy` class.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`cartCompletionStrategy`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Price Selection Strategy
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of the class implementing the `IPriceSelectionStrategy` interface.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
`priceSelectionStrategy`
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
|
||||
Strategies
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
An instance of strategies that aren’t of the specific types mentioned above and that are under the `strategies` directory.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
Its camel-case name.
|
||||
|
||||
</td>
|
||||
<td>
|
||||
|
||||
\-
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
---
|
||||
|
||||
## Loading Resources
|
||||
|
||||
This section covers how to load resources that the Medusa backend registers when it starts running.
|
||||
|
||||
### In Endpoints
|
||||
|
||||
To load resources, such as services, in endpoints, use the `req.scope.resolve` function. The function receives the registration name of the resource as a parameter.
|
||||
|
||||
For example:
|
||||
|
||||
```ts
|
||||
const logger = req.scope.resolve("logger")
|
||||
```
|
||||
|
||||
Please note that in endpoints some resources, such as repositories, are not available.
|
||||
|
||||
### In Classes
|
||||
|
||||
In classes such as services, strategies, or subscribers, you can load resources in the constructor function using dependency injection. The constructor receives an object of dependencies as a first parameter. Each dependency in the object should use the registration name of the resource that should be injected to the class.
|
||||
|
||||
For example:
|
||||
|
||||
```ts
|
||||
import { OrderService } from "@medusajs/medusa"
|
||||
|
||||
class OrderSubscriber {
|
||||
protected orderService: OrderService
|
||||
|
||||
constructor({ orderService }) {
|
||||
this.orderService = orderService
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## See Also
|
||||
|
||||
- [Create services](../services/create-service.mdx)
|
||||
- [Create subscribers](../events/create-subscriber.md)
|
||||
@@ -0,0 +1,194 @@
|
||||
---
|
||||
description: 'Learn how to perform local development in the Medusa monorepo. This includes how to use the dev CLI tool and perform unit, integration, and plugin tests.'
|
||||
---
|
||||
|
||||
# Local Development of Medusa Backend and Monorepo
|
||||
|
||||
In this document, you’ll learn how to customize Medusa’s core and run tests.
|
||||
|
||||
## Overview
|
||||
|
||||
As an open-source platform, Medusa’s core can be completely customized.
|
||||
|
||||
Whether you want to implement something differently, introduce a new feature as part of Medusa’s core or any of the other packages, or contribute to Medusa, this guide helps you learn how to run Medusa’s integration tests, as well as test your own Medusa core in a local backend.
|
||||
|
||||
### Medusa Repository Overview
|
||||
|
||||
[Medusa’s repository on GitHub](https://github.com/medusajs/medusa) includes all packages related to Medusa under the [`packages` directory](https://github.com/medusajs/medusa/tree/master/packages). This includes the [core Medusa package](https://github.com/medusajs/medusa/tree/master/packages/medusa), the [JS Client](https://github.com/medusajs/medusa/tree/master/packages/medusa-js), the CLI tools, and much more.
|
||||
|
||||
All the packages are part of a [Yarn workspace](https://classic.yarnpkg.com/lang/en/docs/workspaces/). So, when you run a command in the root of the project, such as `yarn build`, it goes through all registered packages in the workspace under the `packages` directory and runs the `build` command in each of those packages.
|
||||
|
||||
---
|
||||
|
||||
## Prerequisites
|
||||
|
||||
### Yarn
|
||||
|
||||
When using and developing with the Medusa repository, it’s highly recommended that you use [Yarn](https://yarnpkg.com/getting-started/install) to avoid any errors or issues.
|
||||
|
||||
### Fork and Clone Medusa’s Repository
|
||||
|
||||
To customize Medusa’s core or contribute to it, you must first [fork](https://docs.github.com/en/get-started/quickstart/fork-a-repo) and then [clone](https://docs.github.com/en/get-started/quickstart/fork-a-repo#cloning-your-forked-repository) the [GitHub repository](https://github.com/medusajs/medusa).
|
||||
|
||||
### Install Dependencies and Build Packages
|
||||
|
||||
In the directory of the forked GitHub repository, run the following commands to install necessary dependencies then build all packages in the repository:
|
||||
|
||||
```bash
|
||||
yarn install
|
||||
yarn build
|
||||
```
|
||||
|
||||
### Medusa’s Dev CLI tool
|
||||
|
||||
Medusa provides a CLI tool to be used for development. This tool facilitates testing your local installment and changes to Medusa’s core without having to publish the changes to NPM.
|
||||
|
||||
To install Medusa’s dev CLI tool:
|
||||
|
||||
```bash npm2yarn
|
||||
npm install medusa-dev-cli -g
|
||||
```
|
||||
|
||||
### Set the Location of the Medusa Repository
|
||||
|
||||
In the directory of your forked GitHub repository, run the following command to specify to the dev CLI tool the location of your Medusa repository:
|
||||
|
||||
```bash
|
||||
medusa-dev --set-path-to-repo `pwd`
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Run Tests in the Repository
|
||||
|
||||
In this section, you’ll learn how to run tests in the Medusa repository. This is helpful after you customize any of Medusa’s packages and want to make sure everything is still working as expected.
|
||||
|
||||
### Set System Environment Variables
|
||||
|
||||
Before you can run the tests, make sure you set the following system environment variables:
|
||||
|
||||
```bash
|
||||
DB_HOST=<YOUR_DB_HOST>
|
||||
DB_USERNAME=<YOUR_DB_USERNAME>
|
||||
DB_PASSWORD=<YOUR_PASSWORD>
|
||||
```
|
||||
|
||||
### Run Unit Tests
|
||||
|
||||
To run unit tests in all packages in the Medusa repository, run the following command in the root directory of the repository:
|
||||
|
||||
```bash
|
||||
yarn test
|
||||
```
|
||||
|
||||
This runs the `test` script defined in the `package.json` file of each package under the `packages` directory.
|
||||
|
||||
Alternatively, if you want to run the unit tests in a specific package, you can run the `test` command in the directory of that package.
|
||||
|
||||
For example, to run the unit tests of the Medusa core:
|
||||
|
||||
```bash
|
||||
cd packages/medusa
|
||||
yarn test
|
||||
```
|
||||
|
||||
### Run API Integration Tests
|
||||
|
||||
API integration tests are used to test out Medusa’s core endpoints.
|
||||
|
||||
To run the API integration tests, run the following command in the root directory of the repository:
|
||||
|
||||
```bash
|
||||
yarn test:integration:api
|
||||
```
|
||||
|
||||
### Run Plugin Integration Tests
|
||||
|
||||
Plugin integration tests are used to test out Medusa’s official plugins, which are also stored in the `packages` directory in the repository.
|
||||
|
||||
To run the plugin integration tests, run the following command in the root directory of the repository:
|
||||
|
||||
```bash
|
||||
yarn test:integration:plugins
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Test in a Local Backend
|
||||
|
||||
Using Medusa’s dev CLI tool, you can test any changes you make to Medusa’s packages in a local backend installation. This eliminates the need to publish these packages on NPM publicly to be able to use them.
|
||||
|
||||
Medusa’s dev CLI tool scans and finds the Medusa packages used in your Medusa backend. Then, it copies the files of these packages from the `packages` directory in the Medusa repository into the `node_modules` directory of your Medusa backend.
|
||||
|
||||
:::info
|
||||
|
||||
Medusa’s Dev CLI tool uses the [path you specified earlier](#set-the-location-of-the-medusa-repository) to copy the files of the packages.
|
||||
|
||||
:::
|
||||
|
||||
### Copy Files to Local Backend
|
||||
|
||||
To test in a local backend:
|
||||
|
||||
1. Change to the directory of the backend you want to test your changes in:
|
||||
|
||||
```bash
|
||||
cd medusa-backend
|
||||
```
|
||||
|
||||
2\. Run the following command to copy the files from the `packages` directory of your Medusa repository into `node_modules`:
|
||||
|
||||
```bash
|
||||
medusa-dev
|
||||
```
|
||||
|
||||
By default, Medusa’s dev CLI runs in watch mode. So, it copies the files when you first run it. Then, whenever you make changes in the `dist` directory of the packages in the Medusa repository, it copies the changed files again.
|
||||
|
||||
### Watch and Compile Changes
|
||||
|
||||
While the above command is running, it's recommended to run the `watch` command inside the directory of every package you're making changes to.
|
||||
|
||||
The combination of these two commands running at the same time will compile the package into the `dist` directory of the package, then copy the compiled changes into your local backend.
|
||||
|
||||
For example, if you're making changes in the `medusa` package, run the following command inside the directory of the `medusa` package:
|
||||
|
||||
```bash title=packages/medusa
|
||||
yarn watch
|
||||
```
|
||||
|
||||
Make sure the `medusa-dev` command is also running to copy the changes automatically.
|
||||
|
||||
Alternatively, you can manually run the `build` command every time you want to compile the changes:
|
||||
|
||||
```bash title=packages/medusa
|
||||
yarn build
|
||||
```
|
||||
|
||||
### CLI Options
|
||||
|
||||
Here are some options you can use to customize how Medusa’s dev CLI tool works:
|
||||
|
||||
- `--scan-once` or `-s`: Copies files only one time then stops processing. If you make any changes after running the command with this option, you have to run the command again.
|
||||
|
||||
```bash
|
||||
medusa-dev -s
|
||||
```
|
||||
|
||||
- `--quiet` or `-q`: Disables showing any output.
|
||||
|
||||
```bash
|
||||
medusa-dev -q
|
||||
```
|
||||
|
||||
- `--packages`: Only copies specified packages. It accepts at least one package name. Package names are separated by a space.
|
||||
|
||||
```bash
|
||||
medusa-dev --packages @medusajs/medusa-cli medusa-file-minio
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## See Also
|
||||
|
||||
- [Create a Plugin](../plugins/create.mdx)
|
||||
- [Contribution Guidelines](https://github.com/medusajs/medusa/blob/master/CONTRIBUTING.md)
|
||||
@@ -0,0 +1,156 @@
|
||||
---
|
||||
description: 'Learn about the Transaction Orchestrator used in the core Medusa package. The transaction orchestrator (TO) offers an effective way of managing transactions within an increasingly complex environment.'
|
||||
---
|
||||
|
||||
# Transaction Orchestrator
|
||||
|
||||
In this document, you’ll learn about the Transaction Orchestrator used in the core Medusa package.
|
||||
|
||||
## Introduction
|
||||
|
||||
The transaction orchestrator (TO) offers an effective way of managing transactions within an increasingly complex environment. It supports Medusa’s modularity and composability by handling transactions from different modules rather than one whole system.
|
||||
|
||||
Medusa’s core package uses the transaction orchestrator to enhance the control and management of transactions and workflows across multiple services or modules. It simplifies creating and executing distributed transactions.
|
||||
|
||||
The transaction orchestrator supervises transaction flows and guarantees that successful transactions are executed fully or entirely rolled back in case of failure. With clearly defined steps to Invoke and Compensate actions, the transaction orchestrator follows the separation of concerns principle, providing you with improved control over transactions and workflows.
|
||||
|
||||
---
|
||||
|
||||
## Why Medusa Uses the Transaction Orchestrator
|
||||
|
||||
The transaction orchestrator is a necessity for modular or distributed systems in scenarios where a given workflow involves different modules for several reasons:
|
||||
|
||||
1. **Data consistency:** In a distributed system, maintaining data consistency across different databases becomes challenging. A transaction orchestrator ensures that if any part of the transaction fails, all the previous steps are rolled back (compensated), keeping the data consistent across all involved databases.
|
||||
2. **Coordination:** The transaction orchestrator acts as a coordinator between different modules and their respective servers. It also manages the order of execution and communication between modules, ensuring that each transaction step is executed correctly and at the right time.
|
||||
3. **Simplifying complex workflows:** In a distributed environment, transactions can become complex due to the need to coordinate between different services and databases. A transaction orchestrator simplifies this process by abstracting away the complexities of managing distributed transactions, allowing developers to focus on implementing the business logic.
|
||||
4. **Scalability:** As a system grows, managing transactions across multiple services becomes increasingly difficult. A transaction orchestrator helps with scalability by providing a robust framework for managing distributed transactions, making it easier to maintain and expand the system.
|
||||
|
||||
In addition to the above reasons, there are reasons more relevant in the context of digital commerce which makes it an important addition to Medusa’s toolbox. These reasons are:
|
||||
|
||||
- **Composable architectures:** A transaction orchestrator supports composable architectures, allowing developers to easily combine and reuse modules as needed. This enables the creation of highly customizable commerce applications, tailored to specific business requirements.
|
||||
- **Adoption in legacy systems:** The transaction orchestrator can also facilitate the gradual transition of legacy systems to more modern, distributed architectures. This makes it easier for businesses to adopt and integrate new technologies without having to rebuild their entire infrastructure from scratch.
|
||||
- **Unlocking infrastructure technologies:** With a transaction orchestrator, developers can leverage advanced infrastructure technologies, such as serverless and edge computing. This can lead to improved performance, reduced latency, and increased reliability for commerce applications, resulting in better user experiences and higher customer satisfaction.
|
||||
|
||||
---
|
||||
|
||||
## Example of Using the Transaction Orchestrator
|
||||
|
||||
To better illustrate how the transaction orchestrator works, here’s an example of how it’s used in the multi-warehouse feature that coordinates the flow to create a product variant, creating an inventory item and finally linking both together:
|
||||
|
||||
```ts
|
||||
const createVariantFlow: TransactionStepsDefinition = {
|
||||
next: {
|
||||
action: "createVariantStep",
|
||||
saveResponse: true,
|
||||
next: {
|
||||
action: "createInventoryItemStep",
|
||||
saveResponse: true,
|
||||
next: {
|
||||
action: "attachInventoryItemStep",
|
||||
noCompensation: true,
|
||||
},
|
||||
},
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
The actions are handled by a single function called by the transaction orchestrator:
|
||||
|
||||
```ts
|
||||
async function transactionHandler(
|
||||
actionId: string,
|
||||
type: TransactionHandlerType,
|
||||
payload: TransactionPayload
|
||||
) {
|
||||
const command = {
|
||||
createVariantStep: {
|
||||
invoke: async (data: CreateProductVariantInput) => {
|
||||
return await createProductVariant(data) // omitted
|
||||
},
|
||||
compensate: async (
|
||||
data: CreateProductVariantInput,
|
||||
{ invoke }
|
||||
) => {
|
||||
await removeProductVariant(
|
||||
invoke.createVariantStep
|
||||
) // omitted
|
||||
},
|
||||
},
|
||||
createInventoryItemStep: {
|
||||
invoke: async (
|
||||
data: CreateProductVariantInput,
|
||||
{ invoke }
|
||||
) => {
|
||||
return await createInventoryItem(
|
||||
invoke.createVariantStep
|
||||
) // omitted
|
||||
},
|
||||
compensate: async (
|
||||
data: CreateProductVariantInput,
|
||||
{ invoke }
|
||||
) => {
|
||||
await removeInventoryItem(
|
||||
invoke.createInventoryItemStep
|
||||
) // omitted
|
||||
},
|
||||
},
|
||||
attachInventoryItemStep: {
|
||||
invoke: async (
|
||||
data: CreateProductVariantInput,
|
||||
{ invoke }
|
||||
) => {
|
||||
return await attachInventoryItem( // omitted
|
||||
invoke.createVariantStep,
|
||||
invoke.createInventoryItemStep
|
||||
)
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
return command[actionId][type](payload.data, payload.context)
|
||||
}
|
||||
```
|
||||
|
||||
Note that the implementation of each function was omitted to keep the example short; however, their names are self-explanatory.
|
||||
|
||||
Finally, the transaction orchestrator is instantiated and a new transaction initialized:
|
||||
|
||||
```ts
|
||||
const strategy = new TransactionOrchestrator(
|
||||
"create-variant-with-inventory", // transaction name
|
||||
createVariantFlow // transaction steps definition
|
||||
)
|
||||
|
||||
const transaction = await strategy.beginTransaction(
|
||||
ulid(), // unique id
|
||||
transactionHandler, // handler
|
||||
createProductVariantInput // input
|
||||
)
|
||||
await strategy.resume(transaction)
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Achieving Cleaner Code with the Transaction Orchestrator
|
||||
|
||||
Utilizing a transaction orchestrator results in cleaner code and single-responsibility functions compared to manually managing distributed transactions. This is due to several factors:
|
||||
|
||||
1. **Abstraction:** A transaction orchestrator abstracts the complexity of managing distributed transactions by providing a standardized framework for defining transaction steps, their corresponding compensation actions, and the flow of execution.
|
||||
2. **Separation of concerns:** By clearly delineating the responsibilities of each function, the transaction orchestrator enforces the separation of concerns. Each function is responsible for either the "Invoke" (execution) or "Compensate" (rollback) action, ensuring they perform a single, specific task. This makes the code more readable, maintainable, and testable.
|
||||
3. **Modularity:** By using a transaction orchestrator, the code becomes more modular, as each step in the transaction is encapsulated within its own function. This allows developers to easily modify, add, or remove transaction steps without affecting the overall structure of the transaction.
|
||||
4. **Error Handling:** When handling distributed transactions manually, the code can become convoluted due to intricate error handling logic. The transaction orchestrator simplifies this by automatically managing errors and retries, allowing developers to create cleaner code without the need to address error handling for each step.
|
||||
5. **Reusability:** The transaction orchestrator allows you to define reusable functions for both the "Invoke" and "Compensate" actions, which can be easily reused across different transaction scenarios. This reduces code duplication and ensures that changes to a specific action only need to be made in one place.
|
||||
|
||||
---
|
||||
|
||||
## Handling Complex Workflows with the Transaction Orchestrator
|
||||
|
||||
The Transaction Orchestrator enables developers to create complex workflows for synchronous and long-running tasks that may take a while to receive a response (asynchronous). These workflows can be organized in a way that may not necessarily be transactional, but can still be effectively orchestrated.
|
||||
|
||||
There are several scenarios where asynchronous workflows with long-running steps can be applied using the transaction orchestrator:
|
||||
|
||||
1. **Order fulfillment:** In a commerce system, a workflow might involve creating an order, reserving inventory, charging the customer, generating shipping labels, and updating the shipping status. Some of these steps, such as generating shipping labels or charging the customer, could take a considerable amount of time due to external dependencies like payment gateways and shipping services.
|
||||
2. **Fraud detection and prevention:** fraud detection and prevention workflows might involve analyzing customer data, order patterns, and payment information to identify potential fraudulent activities. These workflows may include time-consuming tasks like querying external fraud detection APIs or applying machine learning models to analyze data.
|
||||
3. **Returns and refunds processing:** In a returns and refunds workflows, several steps may involve long-running tasks, such as receiving returned products, inspecting their condition, updating inventory, and processing refunds. Some of these steps may take a considerable amount of time, especially when dealing with external payment gateways or waiting for products to be returned and inspected.
|
||||
|
||||
In all these examples, workflows are valuable for handling intricate, multistep processes that include tasks taking considerable time or involving external dependencies without immediate responses.
|
||||
Reference in new issue
Block a user